KC-Scraper
----- An open-source proxy scraper able to scrape from almost every website  ----- ###Features
• Threads • Auto remove not reachable websites ----- ###How to use
Install requirements, put your proxysites in sites.txt and start KC-Scraper.py You can use any site, but make sure you are able to see proxys in the website Example site: https://openproxy.space/list/http ----- ###Premades
You can add and delete these as you like if you have good ones open a pull request ----- ###Notice
How to NOT use sites: 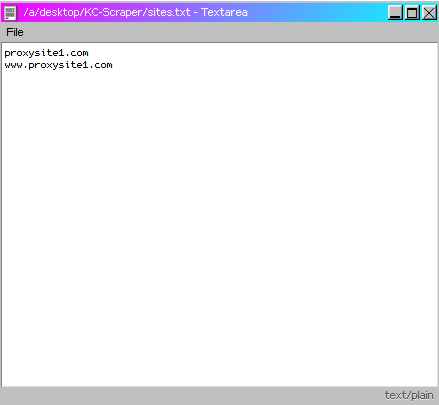 How to use sites: 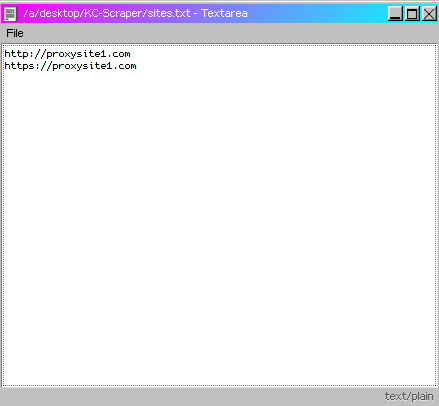 ----- ###Requirements
Python3 or higher `pip install -U -r requirements.txt`